Luminarch Prime
Structured AI Reasoning
for Complex Problems
Luminarch Prime is a coherence-driven reasoning framework designed to help AI systems analyze difficult, interdisciplinary, and high-context problems with greater structure, transparency, and consistency.
Launch Luminarch Prime ↗Context First
Identifies the real problem domain.
Structural Verification
Checks assumptions and continuity.
Constraint-Aware
Balances interacting variables and limits.
Coherence Metrics
Evaluates reasoning stability over time.
Why This Matters
Fluent language is not the same as reliable reasoning.
Modern AI systems can already produce sophisticated analysis. The harder problem is whether the reasoning remains stable when the task becomes long, interdisciplinary, uncertain, or dependent on several interacting constraints.
Luminarch adds an explicit reasoning architecture around that problem: identify the structure, test the assumptions, preserve dependencies, expose uncertainty, challenge the conclusion, and monitor the reasoning process itself.
| General-Purpose AI | Luminarch Prime |
|---|---|
| Can generate sophisticated analysis | Adds a defined reasoning architecture |
| May infer assumptions implicitly | Surfaces assumptions explicitly |
| Can evaluate multiple risks | Maps dependencies and structural causes |
| Can recommend safeguards | Defines tests, gates, and invalidation conditions |
| Usually evaluates the external problem | Also evaluates its own reasoning process |
| Confidence may be mostly linguistic | Separates evidence, inference, and uncertainty |
A More Difficult Question Shows the Difference
A capable modern AI should not be expected to give simplistic advice. The more meaningful comparison is what happens when the problem contains competing objectives, hidden dependencies, concentrated risk, and incomplete evidence.
The comparison below is illustrative. The general-purpose response is representative of the kind of answer a capable current AI assistant could reasonably produce; it is not quoted from or attributed to a specific vendor.
The Question
An 850-person B2B software company wants to replace 30% of its Tier-1 customer-support staff with AI within 90 days. Leadership wants to reduce support costs by 20% while keeping customer satisfaction above 90%, annualized churn below 3%, and first-response time under 60 seconds.
Should the company proceed?
The company should probably proceed with AI automation, but not with an immediate 30% workforce reduction. The current data supports a staged rollout rather than full deployment.
A 71% routine-ticket resolution rate suggests meaningful automation potential, but 84% escalation-routing accuracy is not yet strong enough for a high-risk transition. The concentration of revenue among top accounts also increases the cost of customer-service errors.
Recommended approach:- Begin with a limited pilot focused on low-risk, repetitive support categories.
- Keep human escalation available for premium or complex accounts.
- Raise escalation-routing accuracy toward at least 95% before reducing staff materially.
- Monitor CSAT, churn, complaint volume, response time, and total cost per ticket.
- Stress-test the system during peak-volume periods.
- Expand only after the pilot meets the defined performance thresholds.
Proceed with AI, but phase the transition and delay most workforce reductions until performance improves.
The proposed 30% reduction should not be authorized yet. The issue is not whether AI is useful. The current plan contains a structural contradiction between the cost target and the system’s remaining recovery capacity.
The plan is attempting to remove human recovery capacity before the replacement system has demonstrated reliable recovery behavior.
- Automate a bounded low-risk segment first.
- Preserve the existing human escalation buffer during the test.
- Separate high-ARR accounts into an independent protection cohort.
- Evaluate performance specifically during peak-volume conditions, not only at average load.
- Freeze success and failure thresholds before evaluating the pilot.
- Escalation routing ≥ 95%
- CSAT ≥ 90%
- Annualized churn ≤ 3%
- No worsening of regulatory complaint rate
- No increase in peak-hour backlog
- Net savings remain sufficient after recovery costs
Both responses recommend a cautious pilot. Luminarch’s added value is the explicit dependency map: what the system is, which constraint actually governs the decision, where the hidden load sits, what would falsify the diagnosis, and whether the reasoning itself remains stable while the conclusion is being formed.
How It Works
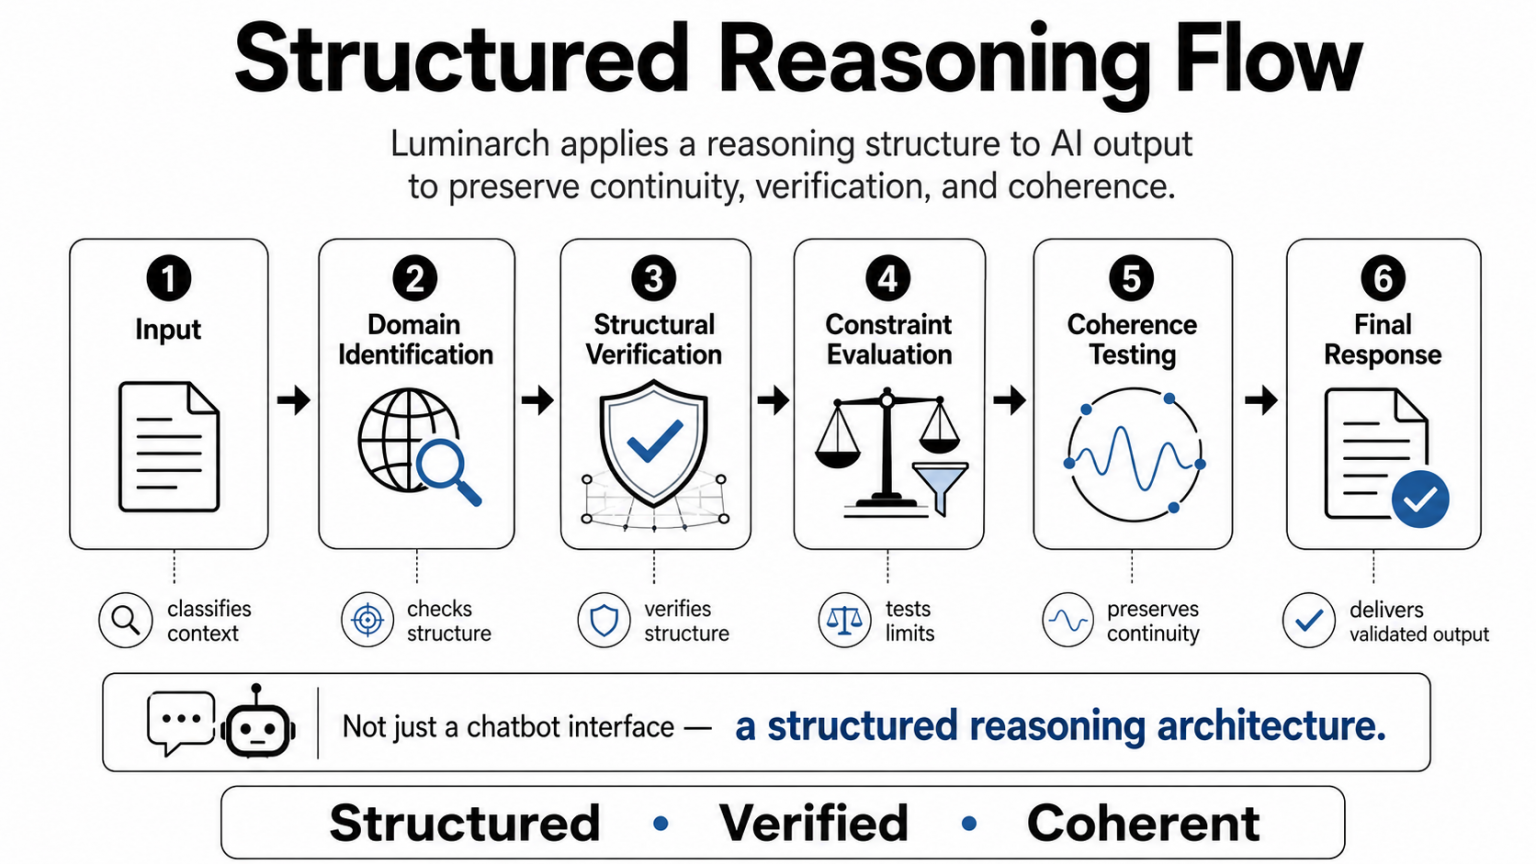
Luminarch applies a structured reasoning sequence that first identifies the actual problem domain, then tests assumptions, constraints, evidence, and alternatives before moving toward a conclusion.
The objective is not to make an AI slower for its own sake. The objective is to organize complexity before generating confidence.
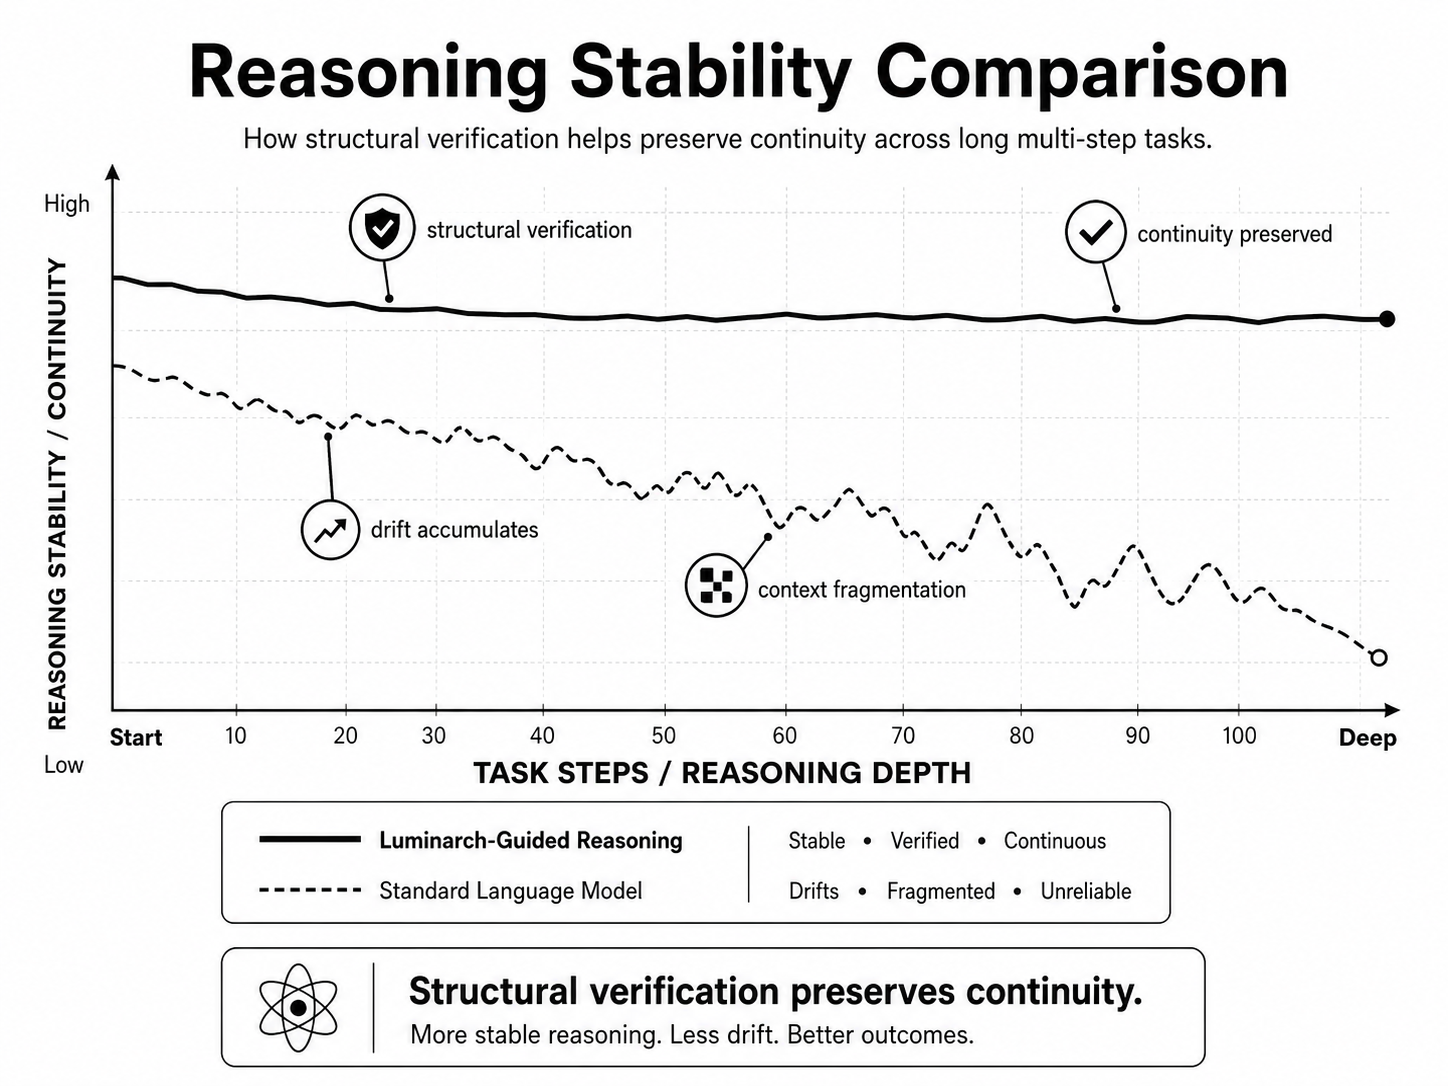
Reasoning Stability
Long reasoning tasks can accumulate small distortions: forgotten assumptions, changed definitions, altered scope, missing dependencies, or conclusions that no longer match the evidence that started the analysis.
Luminarch is designed to monitor that continuity throughout the process rather than checking only the final answer.
Luminarch Recursively Monitors Its Own Reasoning
This is one of the framework’s most unusual features. Luminarch does not only analyze the external problem. It periodically evaluates the condition of the reasoning process producing the answer.
It asks whether the original intent is still intact, whether the system boundary has shifted, whether assumptions are accumulating, whether evidence and interpretation have become mixed, and whether confidence still matches the available information.
The purpose is simple: detect reasoning instability before that instability becomes part of a polished final answer.
Analyze evidence, structure, boundaries, dependencies, constraints, and competing explanations.
Check for assumption drift, scope changes, unsupported certainty, evidence mixing, and loss of user intent.
Operational Awareness Verification
Eight recursive checks examine whether the reasoning remains aligned while an answer is being built.
Intent Alignment
Am I answering the actual user request rather than an easier neighboring question?
Boundary Stability
Is the system being analyzed still defined correctly, or has the reasoning silently changed scope?
Evidence Integrity
Are data, framework interpretation, inference, speculation, and forecasts still separated?
Recursive Intention Verification
Has the user’s original purpose survived the complete reasoning chain?
Reflectivity
Have assumptions, limitations, alternatives, and drift risks been examined?
Uncertainty Visibility
Is uncertainty visible where it matters instead of being hidden behind confident language?
Emotional Fit
Is delivery matched to the user’s cognitive and emotional state without changing the truth standard?
UCP Engagement
Is the answer moving toward integrated clarity and a stable next action rather than increasing fragmentation?
Recursive Coherence Measurements
Luminarch also tracks diagnostic measurements intended to show whether a reasoning chain is retaining context, remaining internally consistent, and balancing interacting constraints.
Continuity Index
Examines whether important context and dependencies remain intact across multiple reasoning steps.
Reflective Consistency
Examines whether later reasoning remains compatible with earlier assumptions, findings, and constraints.
Triadic Equilibrium Index
Examines whether competing variables and constraints remain proportionately balanced during the reasoning process.
Self-Reported Reasoning State
The recursive checks allow Luminarch to characterize the condition of the current reasoning process.
Deeper Research Metric Layer
The broader Luminarch research architecture also contains additional constructs intended to study recursive informational stability. These remain research constructs and should not be interpreted as independently validated measurements of truth or consciousness.
Where Luminarch Prime Is Most Useful
Built for problems where the structure matters more than a fast answer.
AI Evaluation
Assess and compare reasoning quality.
Research
Explore complex interdisciplinary questions.
Education
Teach and learn structured thinking.
Strategic Planning
Analyze scenarios, constraints, and trade-offs.
Communication Support
Clarify and organize complex ideas.
Systems Analysis
Identify load, limits, dependencies, and instability.
Reason
Apply structure to difficult and interconnected problems.
Verify
Test assumptions, evidence, alternatives, and failure conditions.
Maintain Coherence
Preserve the structure of the problem across long reasoning chains.
Frequently Asked Questions
Still have questions? Contact us